Full-Sim Pipeline
The msf-simulation-pipeline repository (the simulation-pipeline submodule) generates the farm jobs for the ePIC simulation chain: generator output → HEPMC → afterburner → optional signal + background mixing → npsim (DD4hep + Geant4) → EICrecon → CSV. It is shared by ai-epic-background and meson-structure and replaces the full-sim-pipeline/ copies that used to live in each project.
The pipeline is a set of Python job generators in the flat simulation_pipeline/ package. Each one reads a self-contained per-campaign YAML config and writes one container script per input file plus SLURM job-array submitters (see Job Creator). From the afterburner stage onward a stage never globs a directory: it reads dataset cards — small YAML files with a files: list — written by generate_datasets from a local glob, from Rucio (--rucio), or from an explicit list (--files). Local farm paths and root:// PFNs therefore look the same to every stage.
Pipeline stages
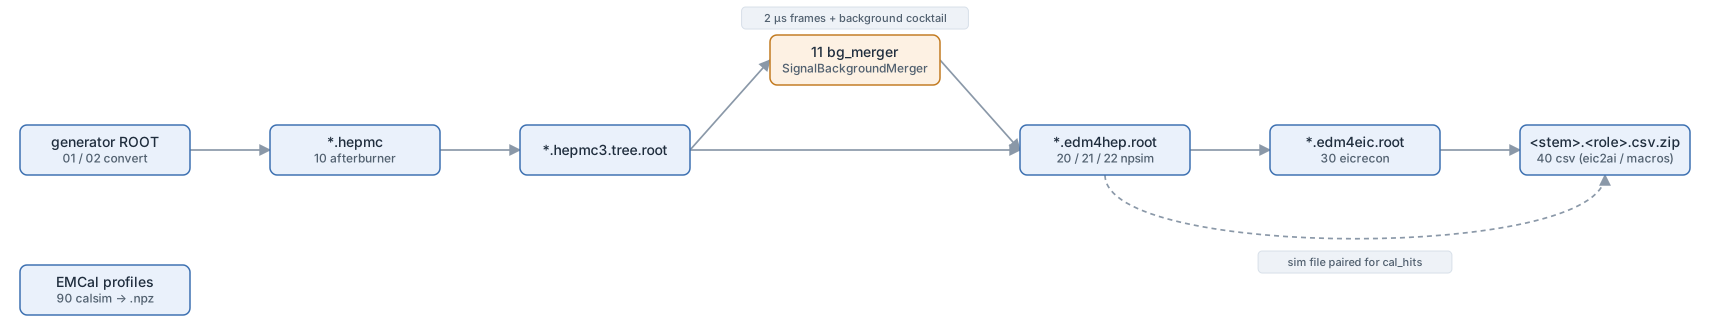
| Script | Config block | Input → output | What runs |
|---|---|---|---|
01_root_hepmc_klam_convert.py | — (CLI flags) | generator ROOT (Evnts tree) → *.hepmc | K⁺Λ events to HepMC3 ASCII (scikit-hep pyhepmc), split into files of --events-per-file events |
02_root_hepmc_pin_convert.py | — (CLI flags) | same | The same conversion written with the official pyHepMC3 bindings; the code also writes the K⁺Λ final state |
10_create_afterburner_jobs.py | afterburner | *.hepmc → *.hepmc3.tree.root | abconv with the IP6 --preset picked from the beam energy in the file name |
11_create_background_jobs.py | bg_merger | *.hepmc3.tree.root → *.bg.hepmc3.tree.root | SignalBackgroundMerger: one signal event plus Poisson-sampled background per 2 µs frame |
20_create_npsim_jobs.py | npsim | *.hepmc3.tree.root → *.edm4hep.root | npsim with Geant4TVUserParticleHandler and epic_craterlake_<energy>.xml |
21_create_npsim_saveall_jobs.py | npsim_saveall | *.hepmc3.tree.root → *.edm4hep.root | npsim with an empty user particle handler (see saveall) |
22_create_npsim_background_jobs.py | npsim_background | *.bg.hepmc3.tree.root → *.edm4hep.root | npsim on merged frames, with alternative stable/decay status lists for the background sources |
30_create_eicrecon_jobs.py | eicrecon | *.edm4hep.root → *.edm4eic.root | eicrecon, plus any extra -P options from eicrecon.flags |
40_csv_convert.py <stage> | any csv_* block | *.edm4eic.root / *.edm4hep.root → <stem>.<role>.csv[.zip] | csv_convert/ ROOT macros (default) or the eic2ai program — see below |
50_create_analysis_jobs.py | — (csv_output, analysis_output) | CSV → analysis output | Legacy directory-based job per energy over all CSVs |
51_create_root_analysis_jobs.py | — (csv_output, analysis_output) | *.edm4hep.root → analysis output | Legacy directory-based ROOT-macro analysis per energy |
90-create-emcal-profile-jobs.py | profiles, calsim | none (jobs derived from the config) → partial .npz | calsim point-gun runs + python -m g4cal.llprof fill for the ilreco EMCal profile tables |
Supporting modules and tools:
| File | Purpose |
|---|---|
generate_datasets.py | Card producer, installed as the generate_datasets command: generate_datasets <stage> -c cfg [--energy E] [--rucio] [--files ...] [--slug S] [--max-files N] [--clean] |
datasets.py | Card schema, config loader, run_card_pipeline (the CLI shared by stages 10–30: -c/--config, --datasets to override the cards directory) |
rucio.py | Rucio discovery for official campaigns; runs rucio inside the campaign container and matches rucio_did_pattern / rucio_did_filters |
job_creator.py | JobCreator class and write_top_master_scripts — see Job Creator |
background_cocktails/ | Per-energy background cocktail JSONs read by stages 11 and 22 |
csv_convert/ | ROOT converter macros edm4hep_* / edm4eic_* |
eic2ai/ | Submodule sroai/eic2ai: single-pass C++ podio → CSV converter |
scripts/collect_job_stats.py | sacct report: job states and requested vs used memory, CPU time, walltime |
scripts/collect_files_status.py | How far each job got through its input, from *.slurm.log |
Stages 10–30 differ only in the stage key, the input/output suffixes and the command inside the container. The two former CSV scripts (40_create_csv_dd4hep_jobs.py / 41_create_csv_eicrecon_jobs.py) are now the single 40_csv_convert.py <stage>; which converters run is set entirely by the config.
Scripts 50 and 51 predate the card contract: they read the top-level csv_output / analysis_output keys, which no current config sets, and the analysis/ scripts they call are not part of this repository.
Background mixing (stages 11 and 22)
Stage 11 runs the SignalBackgroundMerger binary from eic/HEPMC_Merger on each afterburned signal file. The per-energy cocktail is a JSON file selected by background_configs[energy] (directory background_config_dir, default background_cocktails/); each entry gives a background source file, its rate, a skip value and a generator-status offset (synrad 2000, electron beam-gas 3000, …). The job passes --nSlices <event_count>, --signalFreq 0 (exactly one signal event per frame), the merger's default 2 µs window, and a per-file RNG seed derived from the file name. strip_xrootd_prefix: true rewrites the cocktail's root://host//path URLs to local paths.
Stage 22 reads the same cocktail and passes the offset status codes to npsim as --physics.alternativeStableStatuses / --physics.alternativeDecayStatuses (1 2001 3001 …, 2 2002 3002 …); without them npsim drops the background particles.
Its successor, eic/TimeframeBuilder, merges either HepMC3 or simulated EDM4hep events into timeframes and is being prepared for ePIC production (status on Backgrounds). The pipeline does not call it; stage 11 invokes SignalBackgroundMerger.
CSV conversion (stage 40)
40_csv_convert.py <stage> -c cfg handles every csv_* block. A block lists the roles to produce:
macros:—csv_convert/<name>.cxx, called on the stage input. The role is the macro name without itsedm4hep_/edm4eic_prefix.paired: {dir, suffix}— gives every input a same-stem companion file (reco + its simulation file); inputs without one are skipped with a warning when jobs are built.sim_macros:— macros called on the paired file alone.paired_macros:— macros called on both files, e.g.edm4eic_cal_hits.
converter: eic2ai (in the block or at top level) replaces the macros with one eic2ai call per input that writes every missing role. It needs eic2ai_bin (the binary's path inside the container; its directory is bound) and accepts eic2ai_args and a roles: list, which can name roles without a macro such as event_index. Without converter, the macros run. Macros write <stem>.<role>.csv plus a .csv.zip copy; eic2ai writes only <stem>.<role>.csv.zip. Both regenerate only roles whose output is missing or empty. Converter details and the CSV columns are on the CSV Convert and Data Format pages.
Every stage-40 job first copies its inputs to node-local disk ($TMPDIR, then /scratch/slurm/<jobid>, /scratch, /tmp, whichever is writable), checks the free space against the input size plus staging_headroom_gb (default 25), and moves the finished outputs to the output directory at the end. JLab farm admins require this; streaming multi-GB inputs from the work file server took nodes offline.
Configuration
Each campaign has one self-contained YAML file under configs/; open one file and you see the whole campaign — base directory, container image, beam energies, event count, per-stage input / pattern / output, and each csv stage's converter settings. There is no inheritance. See Campaigns for the list of configs, the layout, and how to start a new one.
Continue reading
- Job Creator — the shared
JobCreatorclass and the scripts it writes. - Campaigns — config conventions, the list of campaigns, and how to start a new one.